What has been measured so far, how organisations can evaluate a method in stages, and the research that bears on operational planning.
This page keeps the programme's testing record and evaluation design, and the research that bears on operational planning. The practical starting point is the Productivity Protocols page; individuals and teams can measure their own gains with the two-week self-test.
The earlier protocols
Before settling on the six habits, the programme published eight detailed workflow protocols. Each is an open work contract for an AI assistant, and each remains available, with its full test record, in the protocol library.
Decisions already made, obligations, deadlines, open questions and next actions, each traced to its source passage. The recommended first method: low risk and easy to check.
A draft contract for a recurring manual process, ready to try and refine.
Three earlier versions of these protocols were benchmarked against the same AI working without them. All three showed no clear gain, and the heavier methods often cost more time and computing without better results. That finding shaped the current advice: simple habits, not elaborate procedures.
Research: exact logistics decisions
These two logistics research lines are the catalogue's nearest bridge from exact mathematics to operational productivity. Both produce inspectable planning objects; neither has been tested in an operating supply chain or shown to save time, labour, or money.
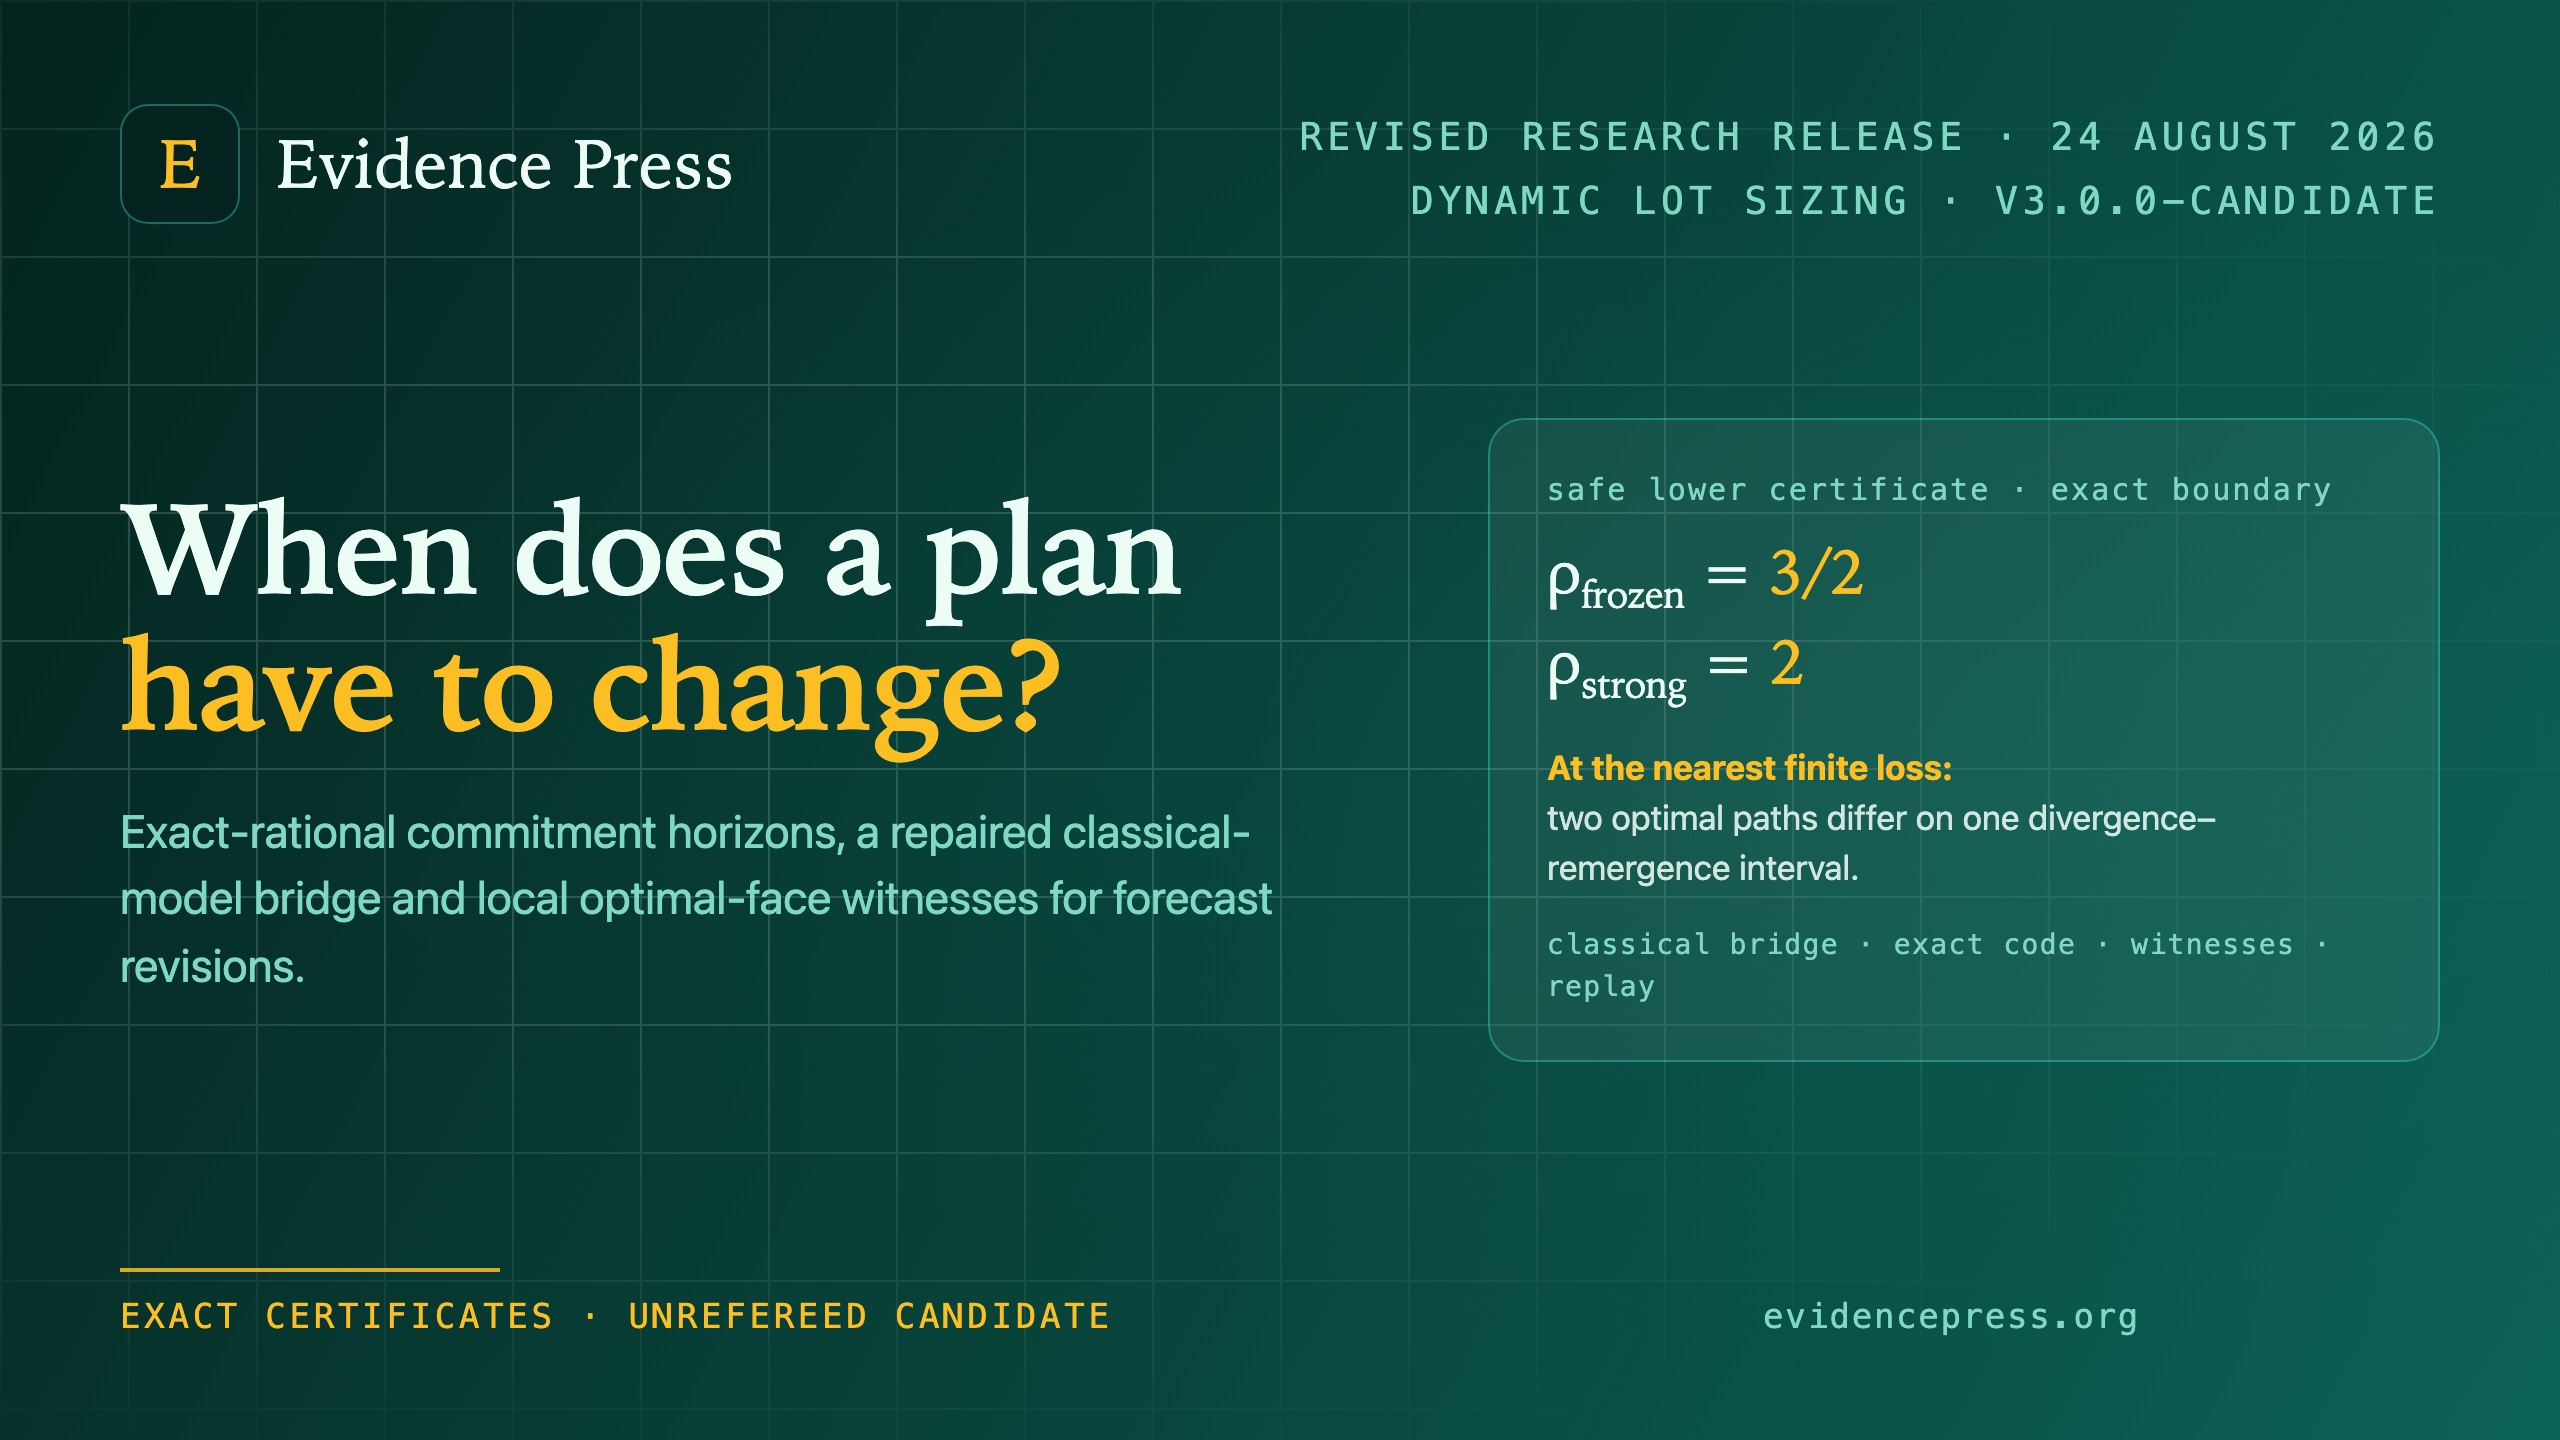
Version 3.0 separates the abstract forced-source path model from its valid classical lot-sizing interpretation, then adds an exact prefix decomposition and local single-detour witnesses for the loss of a protected setup prefix. Its UCI exercise still uses reconstructed forecast vintages and stylised costs; field savings remain unmeasured.
Video briefing — exact three-item joint replenishment
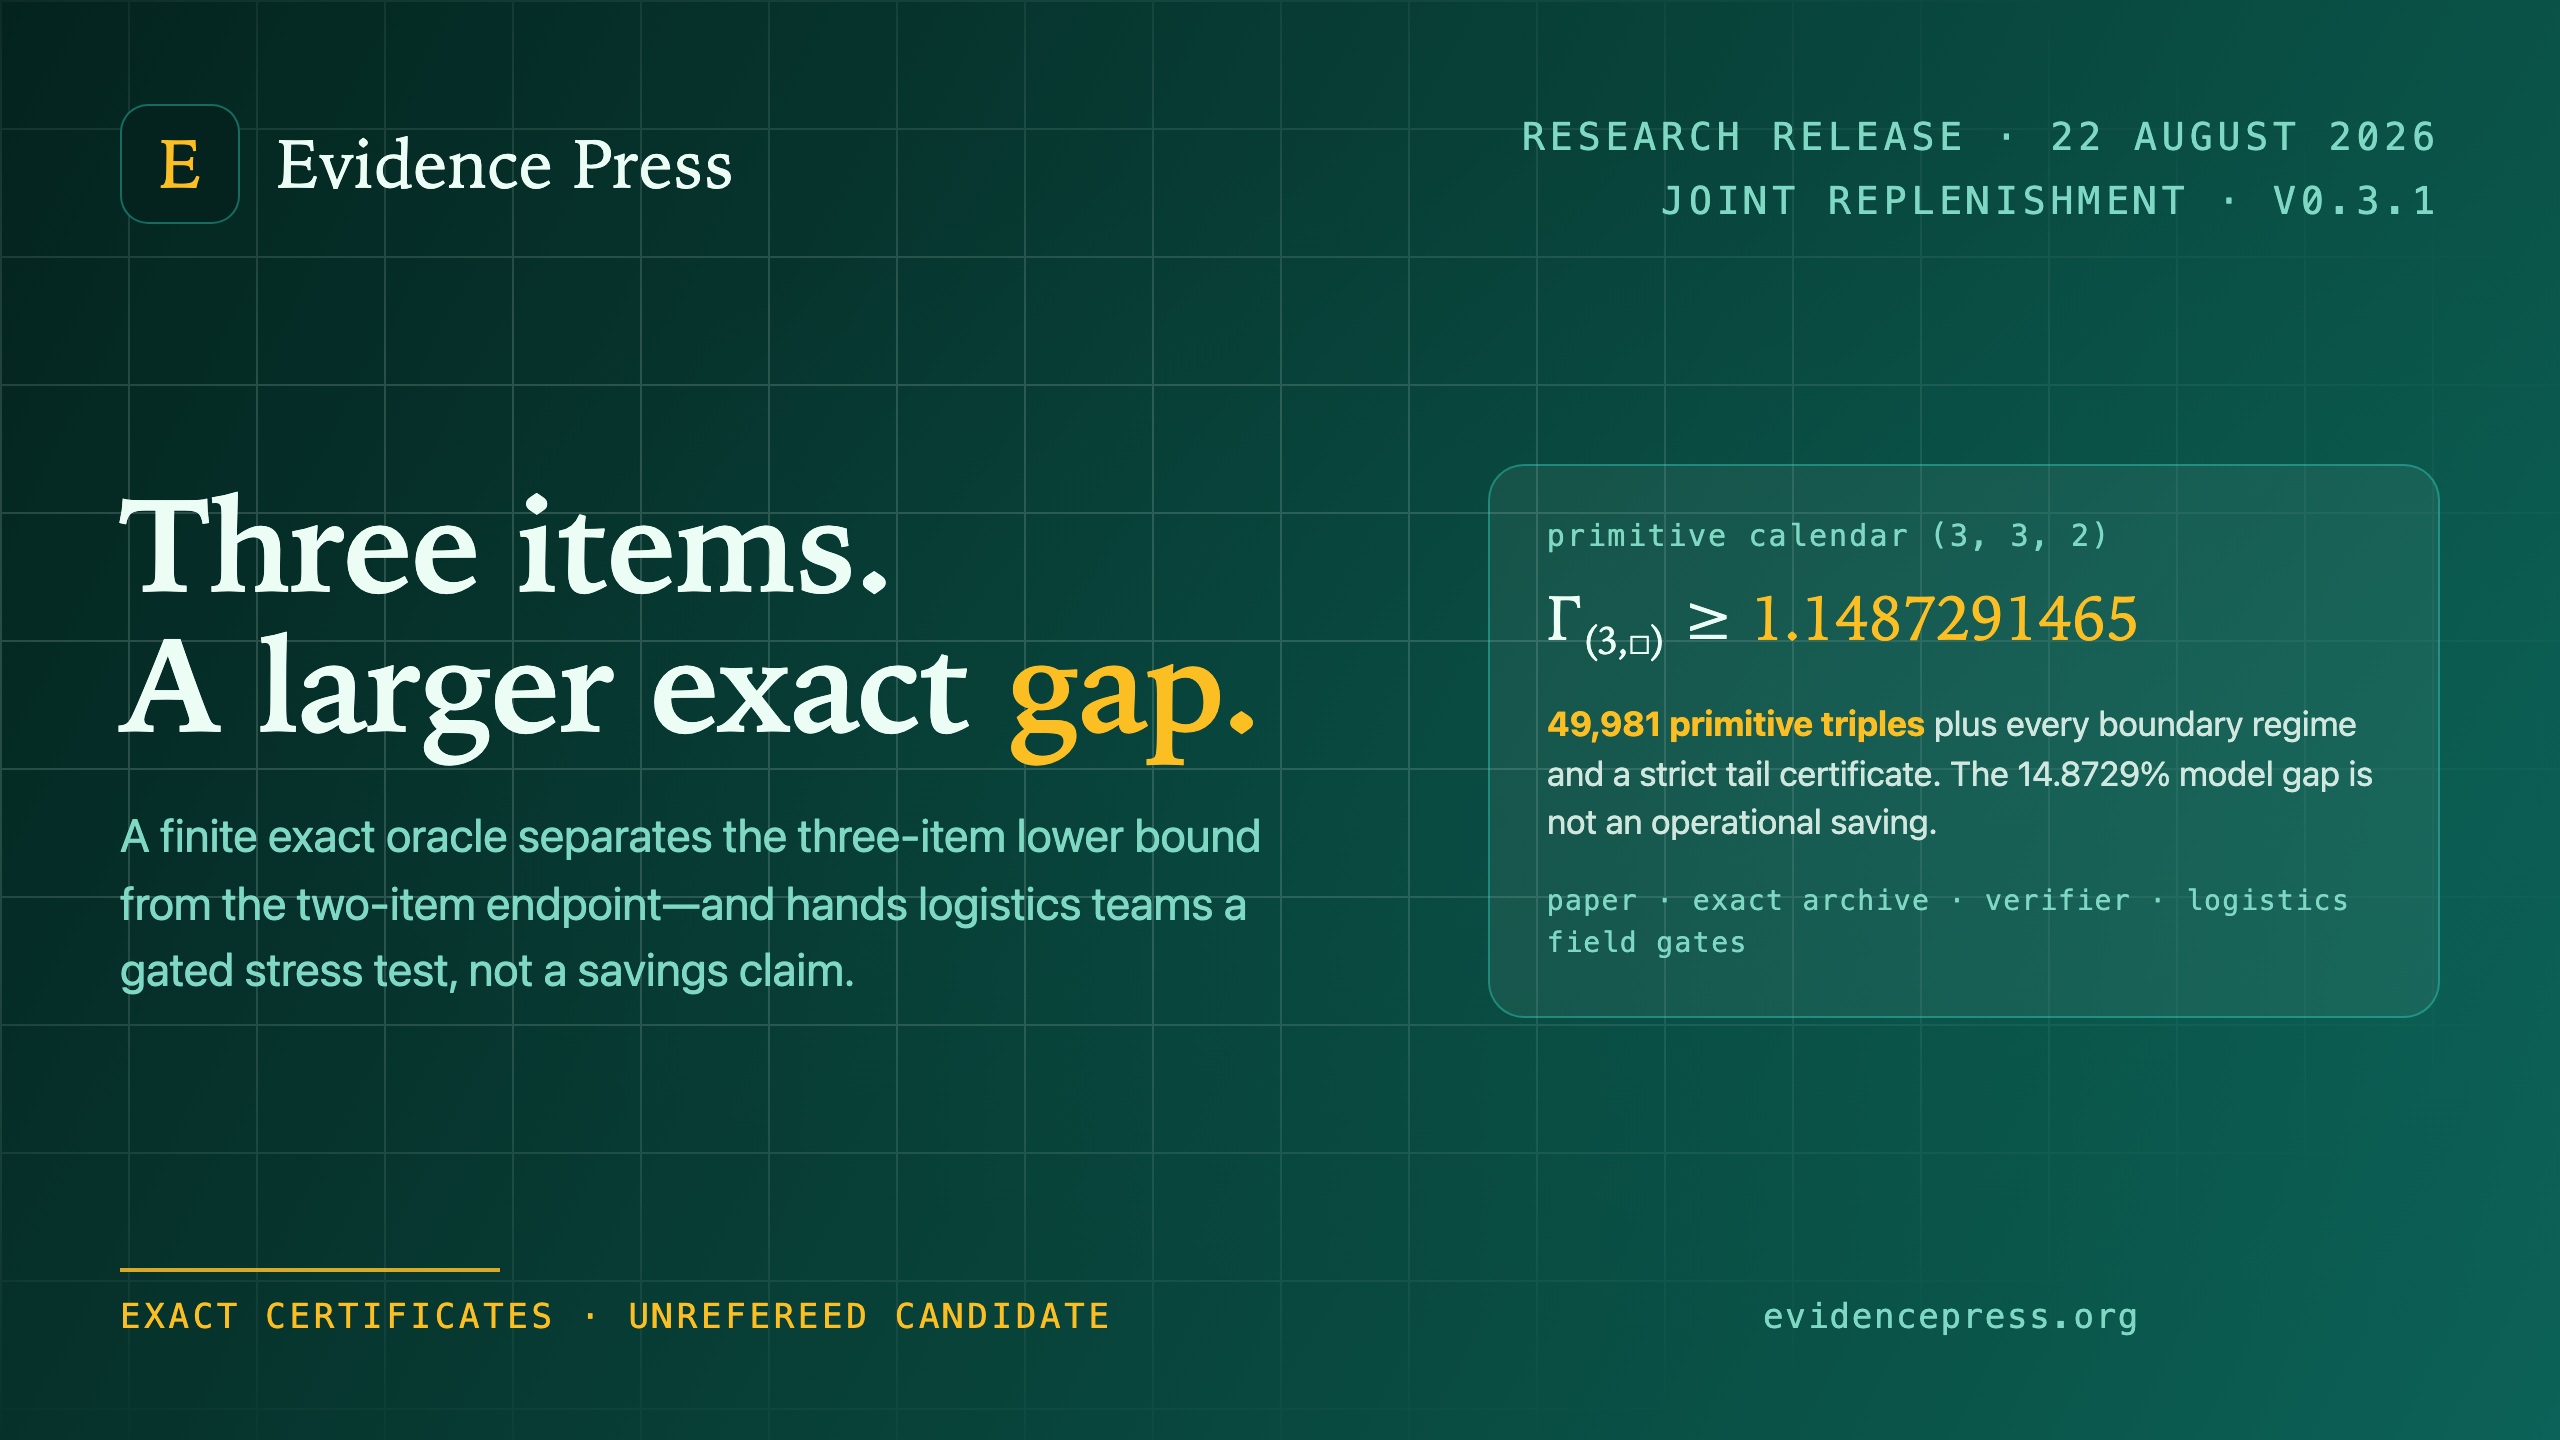
The two-item candidate theorem gives an exact cap-gap constant near 1.111889. Its additive three-item successor reports an exact rational bundled-instance ratio near 1.148729, 3.3132 per cent above the two-item upper endpoint. Within the successor's unrefereed proof-and-replay boundary, the two-item constant is therefore not the unrestricted multi-item answer; the exact three-item constant and every operational benefit remain open.
These are decision-relevant operations results, not productivity impact evidence. The next evidential step is prospective comparison using genuine forecasts, costs and constraints, recording whether the certificates change accepted plans and whether avoided loss or bounded regret exceeds the full human, compute, implementation and assurance cost.
Evidence: what existing tests show
Three version 0.1.0 predecessor protocols have model-output benchmarks. They compare an agent with and without the protocol on small registered task sets. All three record NO_CLEAR_GAIN; the heavier methods often cost more tokens or model time without improving judged output. The changed 0.1.1 packs do not inherit those badges and remain unmeasured until retested.
No person completed a work item in those benchmarks. Human effort, time to accepted work, rework, cognitive burden, support labour, tool cost in company use, adoption, and organisational outcomes were not measured. On human or company productivity, the honest result is no evidence in either direction.
Evidence: choose the right stage
Stage
Starting condition
What it may answer
It must not justify
Formative usability
1–5 consenting participants
Can people understand, operate, review, and safely stop the method?
A productivity effect or adoption based on one
Feasibility
At least six participants and a frozen task bank
Can allocation, measurement, support, cost capture, and retention work?
A powered benefit claim; effects remain exploratory
Controlled evaluation
A justified sample and independently reviewed design
Is there a context-bound incremental signal versus the same agent without the protocol?
Transfer to other companies, tasks, models, or risks
Organisational follow-up
Governed ordinary use after a separate deployment decision
Do use, burden, costs, errors, and outcomes persist here?
Causal attribution unless the identification design supports it
Protocol exposure teaches a structure that people may not be able to unlearn. The included three-period crossover is therefore a feasibility rehearsal only. A future controlled evaluation should use randomized parallel agent-only and protocol-guided groups, with manual work as a secondary operational baseline.
Practice: a protocol is a work contract
A prompt is a suggestion. A protocol states the whole contract: the task and evidence boundary, what the agent may read or change, where a person must approve, how outputs are checked, what counts as failure, and when to stop. It ships as an open Agent Skill that can be inspected without installation.
Practice: keep assurance and impact separate
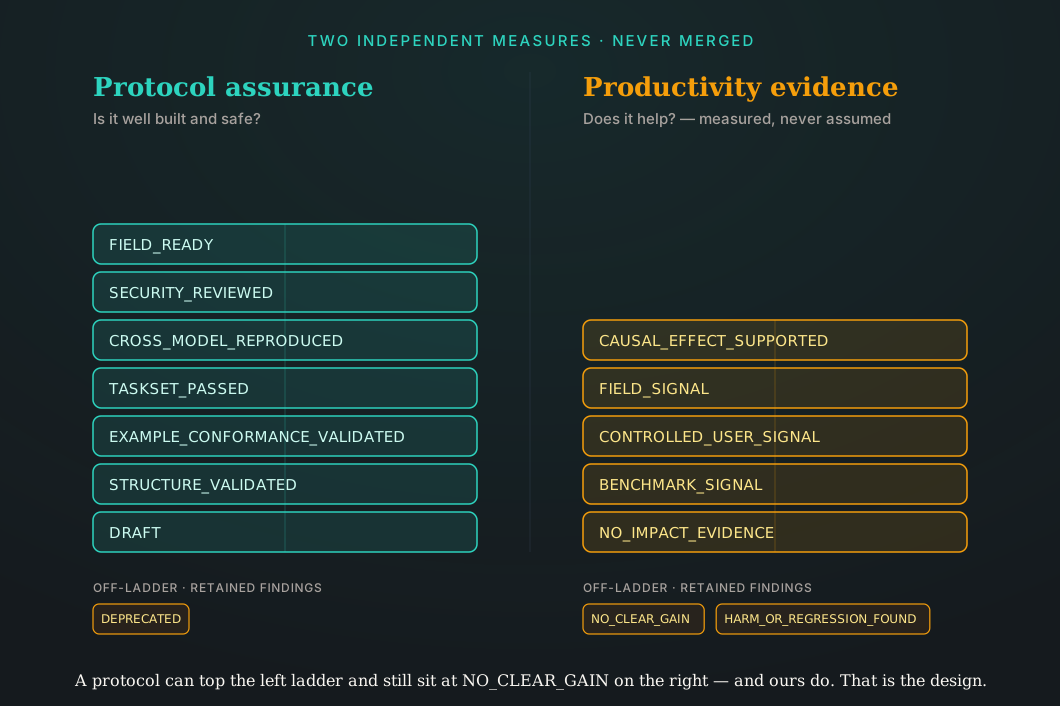
Protocol assurance asks whether the pack is well formed and whether its declared checks pass. It does not establish human benefit or safe use in every setting.
Work evidence asks what was measured: agent-output benchmark, controlled-user signal, organisational field association, or an identified effect. Setting and identification are recorded separately.
Two independent measures, kept apart. Engineering checks cannot borrow the credibility of human-impact evidence, and an observed benefit cannot excuse a poorly bounded protocol.
Start a company trial
The starter kit provides the suitability screen, worker information, frozen plan, task bank, allocation, observation and follow-up records, quality rubric, incident card, semantic validator, and synthetic mutation controls. It keeps missing work items and negative findings instead of deleting them.
Build and hash checks establish inspectability and replay within their declared boundary; they do not establish independent review, field readiness or company impact.